AI WEB EXTRACTION
deepcrawler.ai
An interactive web extraction tool that turns page content into answers to a user-defined extraction prompt, using Selenium and a local language model.
- Python
- Selenium
- BeautifulSoup
- Streamlit
- LangChain
- Ollama
At a glance
- Interface
- Streamlit
- Local model
- Llama 3.1 8B
- Text chunks
- Up to 6,000 characters
- Repository example
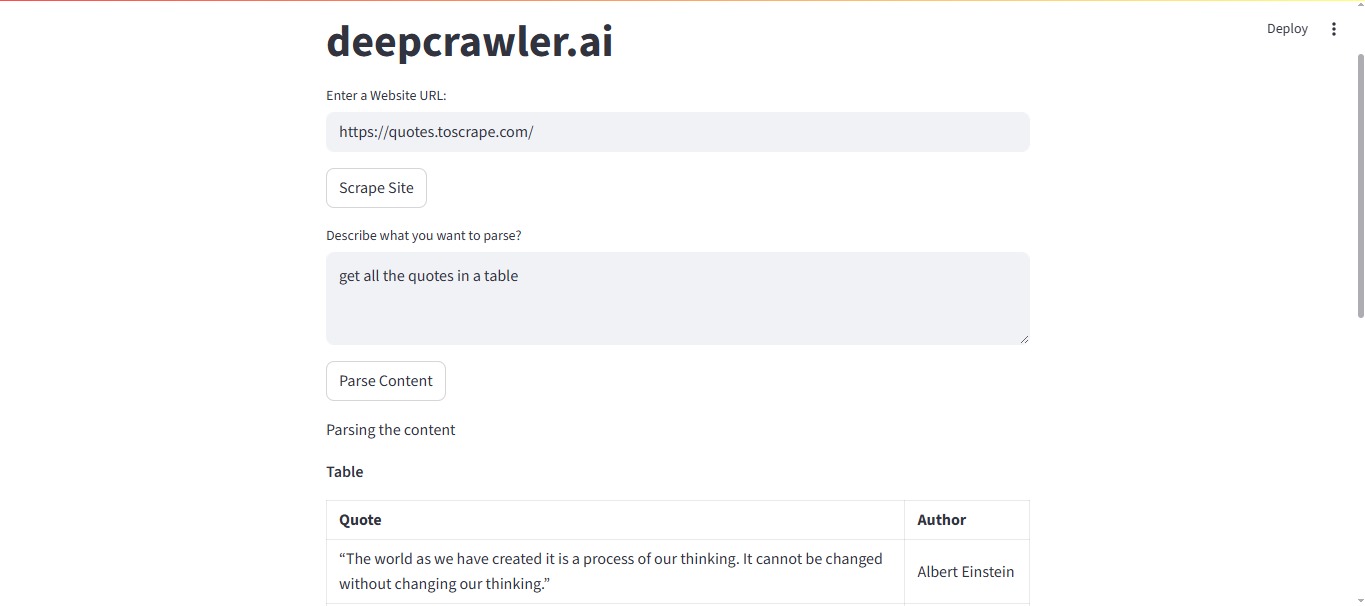
- Quotes extracted into a table
The problem
Web pages contain useful information mixed with navigation, scripts, and styling. Extracting just the relevant information often means writing a new parser for each task.
What I built
Built a modular Python application that captures a page with Selenium, cleans its body text with BeautifulSoup, and sends text chunks plus an extraction request to a local Ollama model through LangChain.
How it works
- Enter a URL and capture the page HTML using Selenium and Chrome.
- Remove scripts and styles, clean whitespace, and inspect the extracted text in Streamlit.
- Describe the information to extract and split the text into chunks of up to 6,000 characters.
- Process each chunk with Llama 3.1 8B through Ollama and display the combined responses.
Outcome
A Streamlit workflow for scraping, inspecting page text, and extracting requested information.
Limitations
- Requires a local Ollama model and a compatible Chrome driver; the current driver path targets Windows.
- The scraper captures one requested page at a time. Automatic multi-page crawling is not implemented.
- Extraction quality depends on the captured page content, prompt, and model. Generated output needs review; no accuracy benchmark is provided.